Soft 404s: how a successful HTTP response can erase a page from search
Distinguish true 404s, soft 404s, valid empty states, redirects, and transient failures, then enforce correct HTTP semantics across server-rendered and single-page applications.
Deep technical guides on crawl setup, rendering parity, report analysis, and crawl-led troubleshooting.
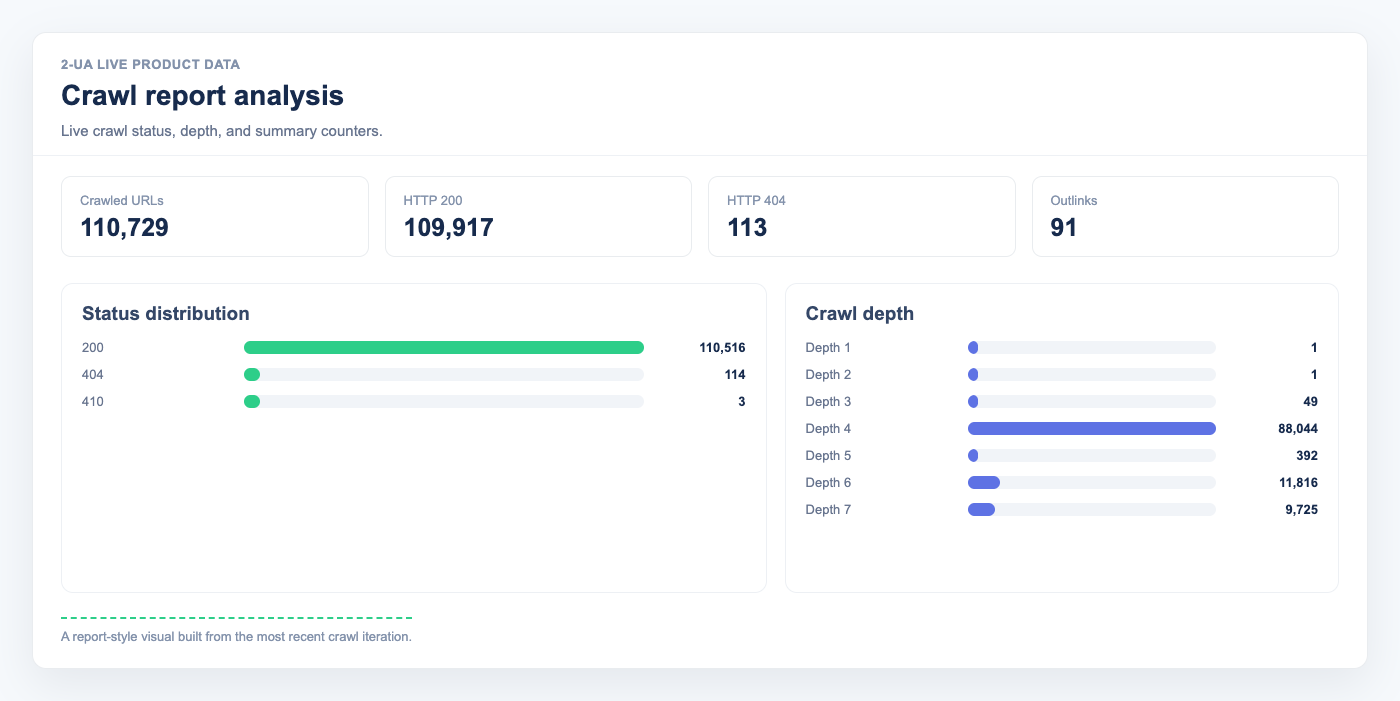
Distinguish true 404s, soft 404s, valid empty states, redirects, and transient failures, then enforce correct HTTP semantics across server-rendered and single-page applications.
Decide what must be server-rendered, test source and rendered parity, and diagnose failures caused by the 2 MB fetch boundary, hydration, state, resources, and status handling.
Find structurally important but weakly connected pages, choose links that improve navigation and discovery, and test the change without inventing link-juice precision.
Choose the right evidence for HTTP requests, rendering, indexed URL state, and search performance, then join the sources without forcing unlike totals to match.
Reconstruct the duplicate cluster, expose conflicting redirects, canonicals, sitemaps, links, and content, then choose the URL control that fits the resource.
Determine whether crawl budget is a real constraint, separate demand from capacity, and choose the intervention that can change the measured bottleneck.
See when JavaScript or user-agent handling changes titles, canonicals, robots directives, headings, schema, links, or visible content.
A no-fluff guide to user agent, JS rendering, robots rules, headers, and crawl strategy choices.
Turn raw crawl data into action using query operators, segment filters, and practical triage logic.
Find parity issues between classic and JS-rendered versions, and between device profiles.
Use crawl-derived outbound links and top word reports to spot quality and relevance issues quickly.
Track sitemap history and daily page count changes both site-wide and per individual sitemap file.
Run a free crawl, understand your baseline issues, then scale into full monitoring when needed.
Every page snapshot 2-UA takes with 2-UAcomBot is gated by the target host's robots.txt. Here is exactly how our bot behaves and how to control it.
Crawl your site, filter 4xx/5xx, export to XLSX, and set up auto-alerts so broken links never reach users again.
Find every redirect chain longer than one hop, fix loops, and recover crawl budget Googlebot is wasting on 302/301 ping-pong.
Combine a full crawl with your sitemap and GSC export to surface every page Google knows about but your site does not link to.